Field notes / AI Coding
I Built an Autonomous Coding Swarm. Here's What I Learned.
This isn't a post about replacing developers. I'm a developer. I like being employed. This is about what happens when you stop treating AI coding tools as fancy autocomplete and start treating them as actual teammates.
Let me be clear upfront: this isn't a post about replacing developers. I'm a developer. I like being employed. This is about what happens when you stop treating AI coding tools as fancy autocomplete and start treating them as actual teammates.
I've been building a system called Hive—an orchestration layer that turns Linear issues into pull requests without me touching the keyboard. Not for every task. Not for architecture decisions. But for the 60% of implementation work that's straightforward once you know what to build.
Here's the honest breakdown.
The Problem No One Talks About
I was using Claude Code daily. Cursor before that. GitHub Copilot before that. Each one made me faster. But I kept hitting the same wall: context switching.
The workflow looked like this:
- Open Linear, read the issue
- Open the codebase, remember where everything lives
- Open Claude, explain the codebase again
- Implement the thing
- Go back to Linear, update the status
- Open GitHub, create the PR
- Repeat 47 times per week Every task required me to be the glue. I was a human API, translating between systems that should already be talking to each other.
The question became obvious: what if they just... did?
How Hive Works
The architecture is simpler than you'd expect.
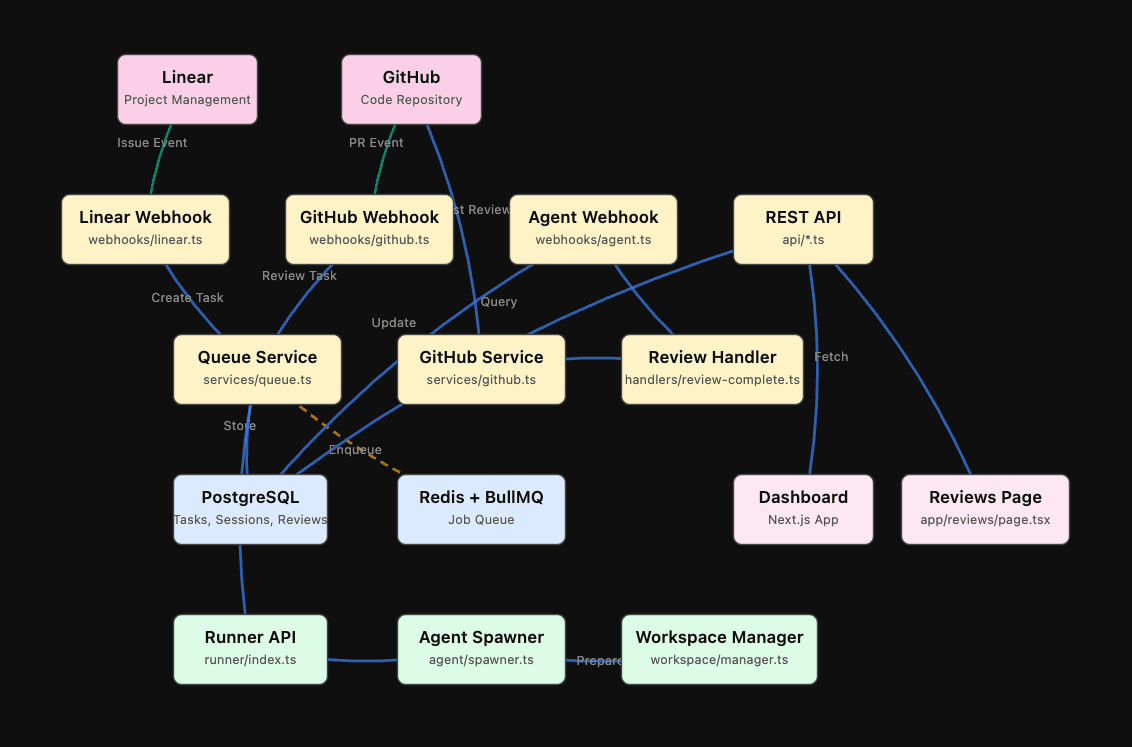
Linear is the source of truth. When an issue moves to "Ready for Agent," a webhook fires. That's the trigger.
Orchestrator receives the webhook, parses the issue, and creates a task. It figures out which repo, what complexity, which model to use. Then it queues the work.
Queue ensures one agent per repo at a time. No merge conflicts from parallel work on the same codebase. Tasks wait their turn. First in, first out.
Runner spawns the actual Claude Code process. It clones the repo, creates a branch, builds a prompt with full project context, and lets the agent work.
Claude Code does the implementation. It reads files, writes code, runs tests, creates commits. When it's done, it opens a PR and reports back.
Linear gets updated automatically. Issue moves to Done. PR link attached. Summary added as a comment.
The whole loop runs without my involvement. I review the PR when I'm ready. That's it.
Win
The entire workflow completes autonomously, from issue to PR.
The Parts That Actually Matter
Repository Onboarding
This was the unlock. Every time you point Claude at a new codebase, it has to rediscover everything. Where are the tests? What's the folder structure? Is this TypeScript strict mode? Every. Single. Time.
Hive runs an onboarding pass when it first encounters a repo. It analyzes:
- Tech stack (languages, frameworks, tools)
- Directory structure and entry points
- Available commands (dev, build, test, lint)
- Coding conventions from existing patterns
- Key files and their purposes This gets stored and injected into every prompt for that repo. The agent starts with context instead of spending tokens figuring out basics.
Win
Repository context is cached and reused, eliminating repetitive discovery.
Skills System
Different tasks need different knowledge. A PR review needs security awareness. A Next.js feature needs App Router patterns. A database migration needs Prisma conventions.
Skills are markdown files that get loaded into the prompt based on task type:
skills/
  code-review.md      # Security checklist, auto-fix guidelines
  nextjs-patterns.md  # App Router, Server Components, best practices
  testing.md          # What to test, how to structure specs
  typescript.md       # Strict mode, type conventions
The agent doesn't have to re-learn best practices every time. They're already in context.
Win
Domain knowledge is modular and task-specific.
PR Code Reviews with Auto-Fix
This one excites me. When a PR is opened on a connected repo, Hive:
- Checks out the PR branch
- Reviews for security issues, performance problems, code quality
- Fixes what it's confident about
- Commits and pushes to the same branch
- Posts a summary comment The auto-fix part is key. Most code review comments are "add error handling here" or "this should be typed." The agent just does it. Pushes the commit. Moves on.
Human reviewers focus on architecture and logic. The tedious stuff is already handled.
Win
Auto-fixing shifts human focus to high-value review tasks.
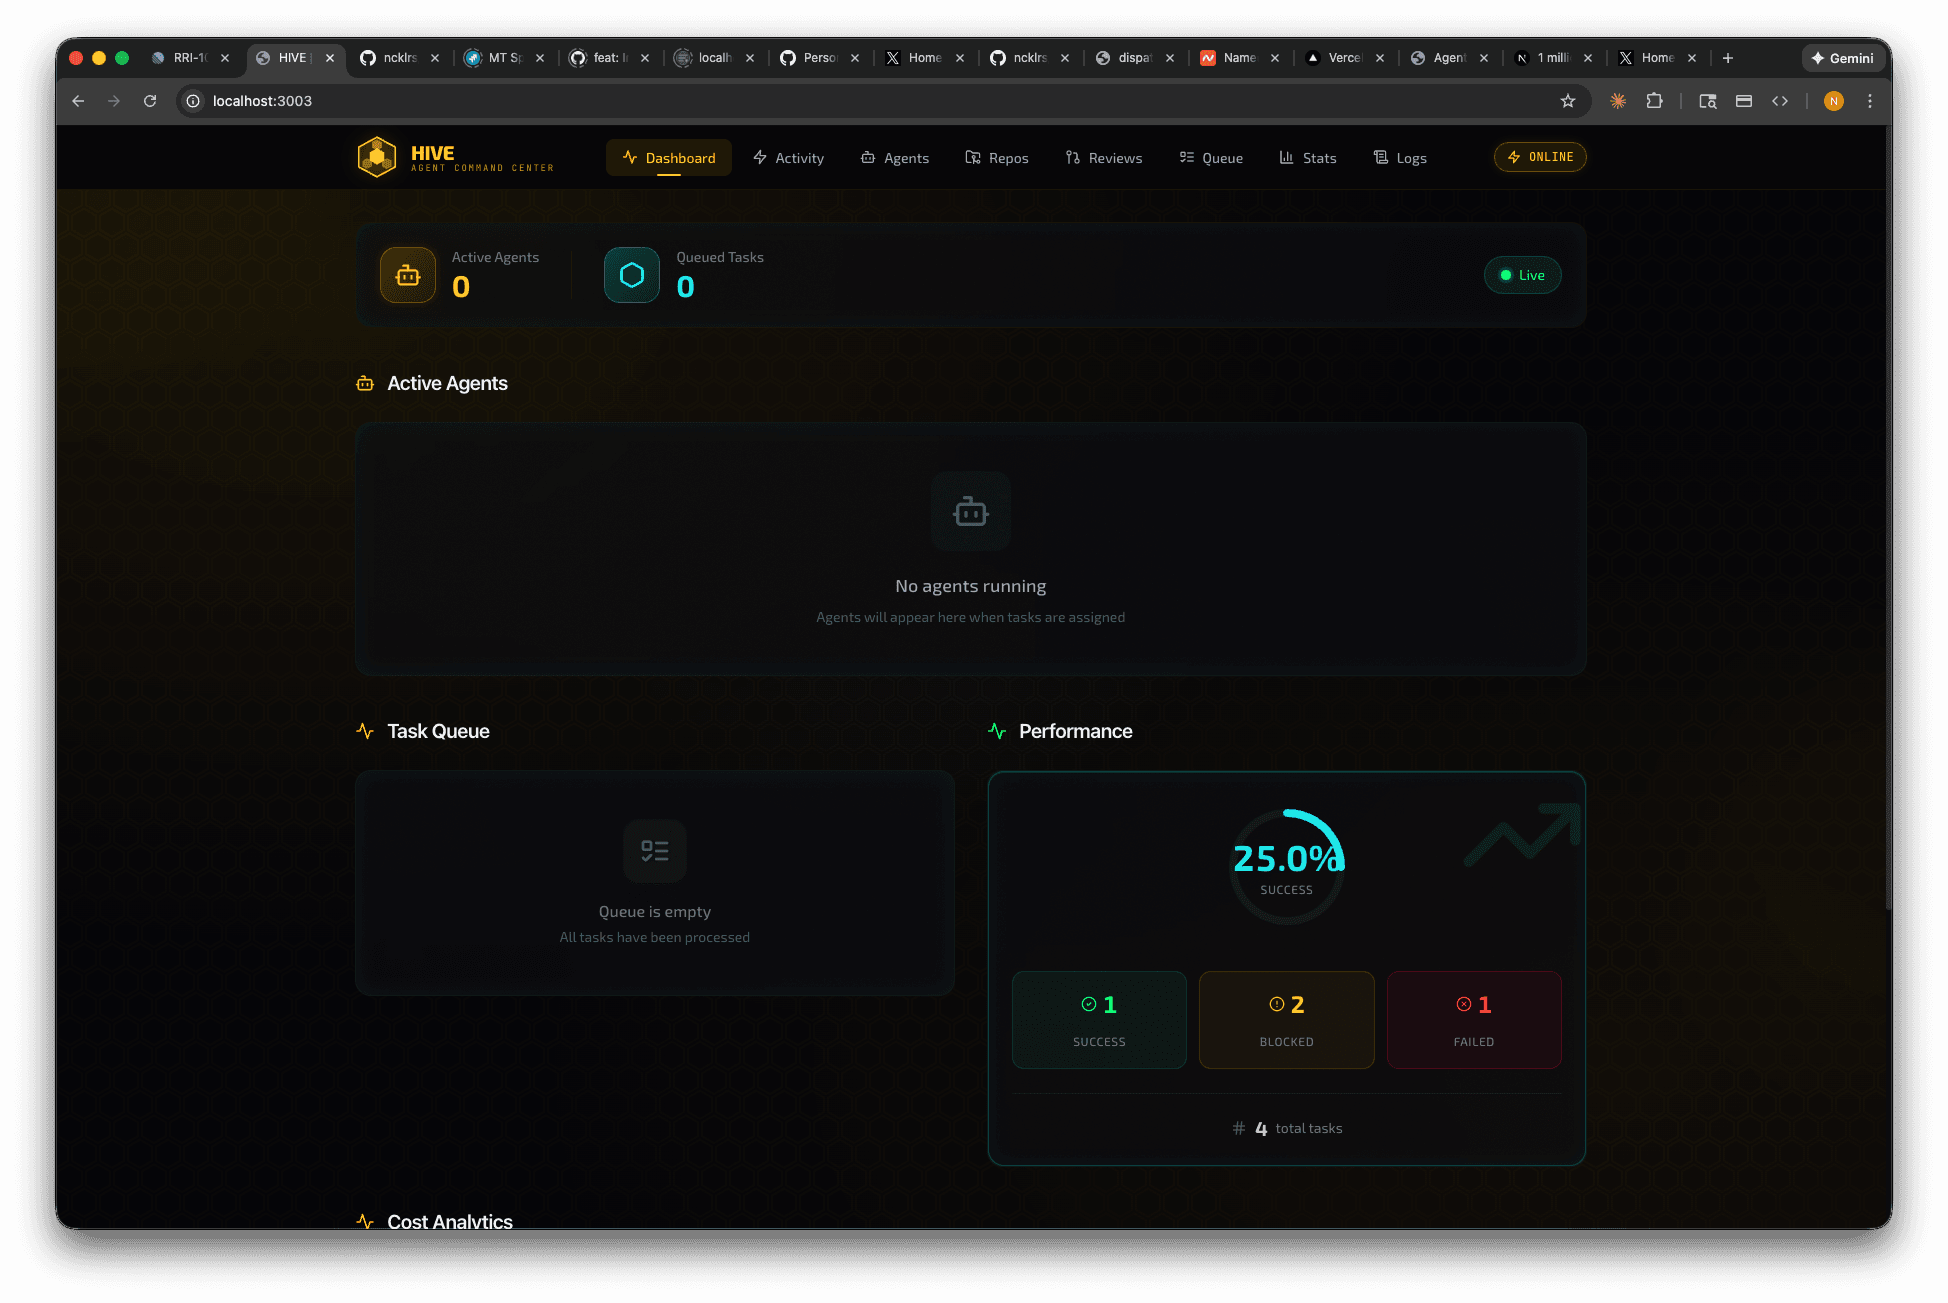
The Dashboard
Real-time visibility into everything:
- Active agents and their current status
- Queued tasks waiting for execution
- Code reviews in progress
- Cost tracking per task and daily aggregates
- Success rates and failure patterns I can see exactly what's running, what's waiting, and what failed. No black box.
Win
Full visibility into the autonomous workflow.
The Honest Limitations
It's Not Magic
The agent is as good as the issue description. Vague requirements produce vague implementations. "Make the button better" is not a task specification.
I write more detailed issues now. Not for the agent—for clarity. Turns out that's just good practice anyway.
Trade-off
Bummer that it requires effort. Win that it forced better habits.
Complex Tasks Still Need Humans
Multi-system refactors. Performance optimization without clear metrics. Anything requiring product judgment. These aren't agent tasks.
Hive works best for well-scoped implementation: add this endpoint, create this component, fix this bug, write these tests. The 60% of work that's clear once you've made the decisions.
Trade-off
Bummer. But also: that's the right boundary.
Failure Happens
Agents get stuck. Tests fail. The implementation misses edge cases. This isn't a "set and forget" system.
The difference is visibility. When a task fails, I see it immediately in the dashboard. The logs show exactly where it went wrong. I can fix the issue, update the prompt, and retry—or just handle it manually.
Trade-off
Bummer that it fails. Win that failures are obvious.
The Math
Let's be concrete. Average implementation task takes me 45 minutes:
-
10 min: context gathering, reading related code
-
25 min: actual implementation
-
10 min: PR creation, Linear update, cleanup With Hive, that same task takes me 5 minutes:
-
3 min: write a clear issue description
-
2 min: review the PR when it's ready That's an 8x reduction in my active time per task. For 10 tasks per day, that's 400 minutes saved. Nearly 7 hours.
Reality check: not every task is suitable. Maybe 60% of my backlog fits this model. And I still need to review PRs—that's intentional.
But even at 60% applicability, we're talking 4+ hours per day of reclaimed focus time. Time I can spend on architecture, product decisions, or tasks that actually need human judgment.
Win
8x time reduction on applicable tasks means hours of focus time reclaimed daily.
What This Changes About AI Coding
The industry is stuck on "AI coding assistants." Tools that help you code faster. The mental model is still human-in-the-loop for every keystroke.
Hive flips that. The agent does the work. The human reviews the output. Same pattern as managing a junior developer, except the agent doesn't need coffee breaks and can run at 2 AM.
This isn't about replacing developers. It's about changing what developers spend time on.
Less: typing code, updating tickets, creating PRs, remembering folder structures
More: architecture decisions, code review, product thinking, system design
The bottleneck shifts from implementation speed to decision quality. And that's where humans should be spending time anyway.
The Future Bit
Here's what I think is coming:
Agent specialization. Right now, one agent handles everything. But different tasks benefit from different approaches. A refactoring agent should think differently than a feature agent. Specialized prompts, specialized skills, specialized review patterns.
Multi-agent coordination. Complex features require multiple coordinated changes. Frontend and backend work that needs to align. Today that's manual orchestration. Tomorrow, agents negotiate interfaces and implement in parallel.
Learning from feedback. Every PR review is a training signal. What did the human change? What comments were left? That feedback should improve future runs. Not in a creepy way—just pattern recognition across your own codebase.
Cost optimization. Right now I route tasks to different models based on complexity. Simple tasks get cheaper models. Complex tasks get capable ones. That routing gets smarter with data.
Self-healing pipelines. Agent fails? Analyze the failure. Adjust the approach. Retry. Some failures are recoverable without human intervention.
None of this is science fiction. The pieces exist. It's just engineering work to connect them.
The Uncomfortable Question
"Aren't you automating yourself out of a job?"
No. I'm automating the parts of my job I don't want to do.
I became a developer to solve problems, not to type brackets. Every hour I spend on mechanical implementation is an hour I'm not spending on interesting work.
Hive doesn't replace developers. It changes the job description. Less time implementing, more time deciding. Less time on the predictable, more time on the novel.
That's not a threat. That's progress.
Try It
Hive is still in active development and I am still trying to figure out the direction to take it. The architecture is documented. There's an interactive explorer that maps every component. I wanted to solve problems that I see at my work, and this is on track to do that.
Will it work perfectly for every codebase? Probably not immediately. Every team has different conventions, different standards, different definitions of "done."
But the pattern is transferable. Webhooks in, agents out, humans reviewing. That loop works regardless of your specific tech stack.
The future of coding isn't AI writing all the code. It's AI handling the predictable parts while humans focus on the hard stuff.
We're already there. The tools exist. It's just a matter of connecting them.
Hive is not yet available. The architecture playground will be made available soon. Questions and contributions welcome.
If you want to build a strong foundation before going autonomous, start with building a production-grade Claude Code workflow and optimizing your CLAUDE.md documentation.
The system at a glance
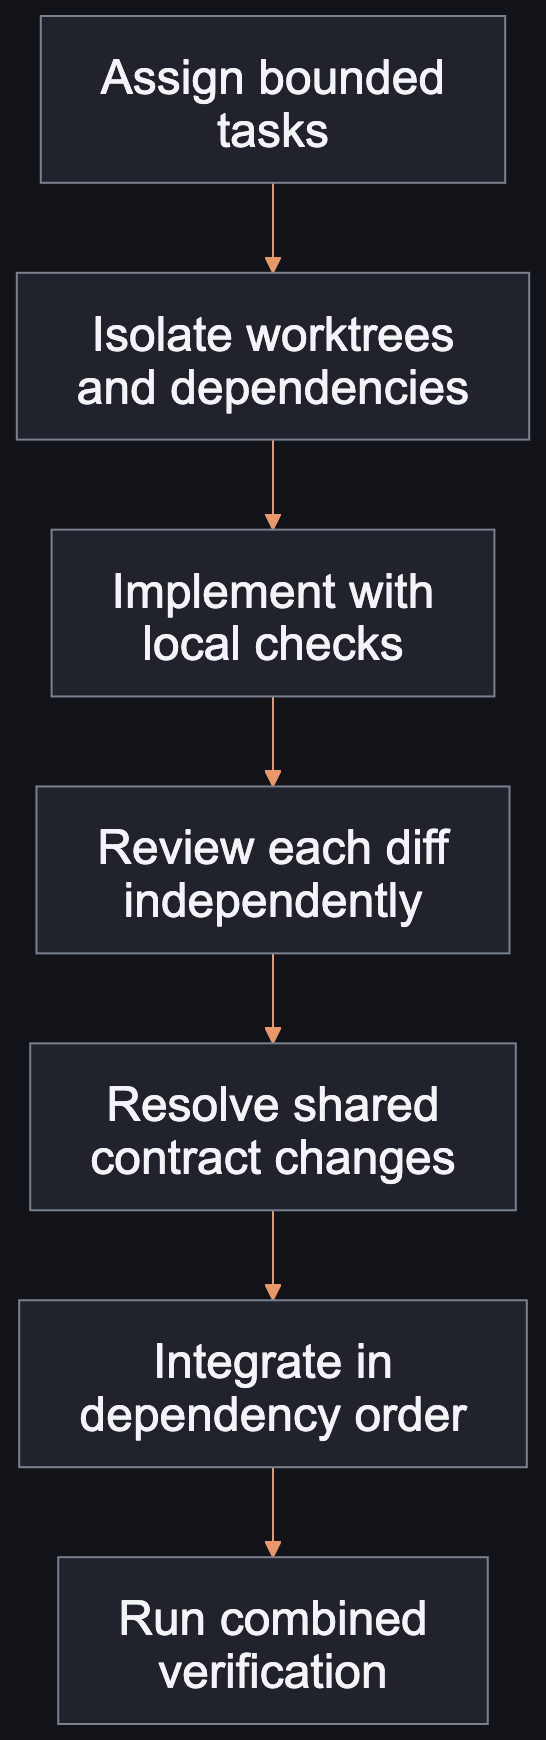
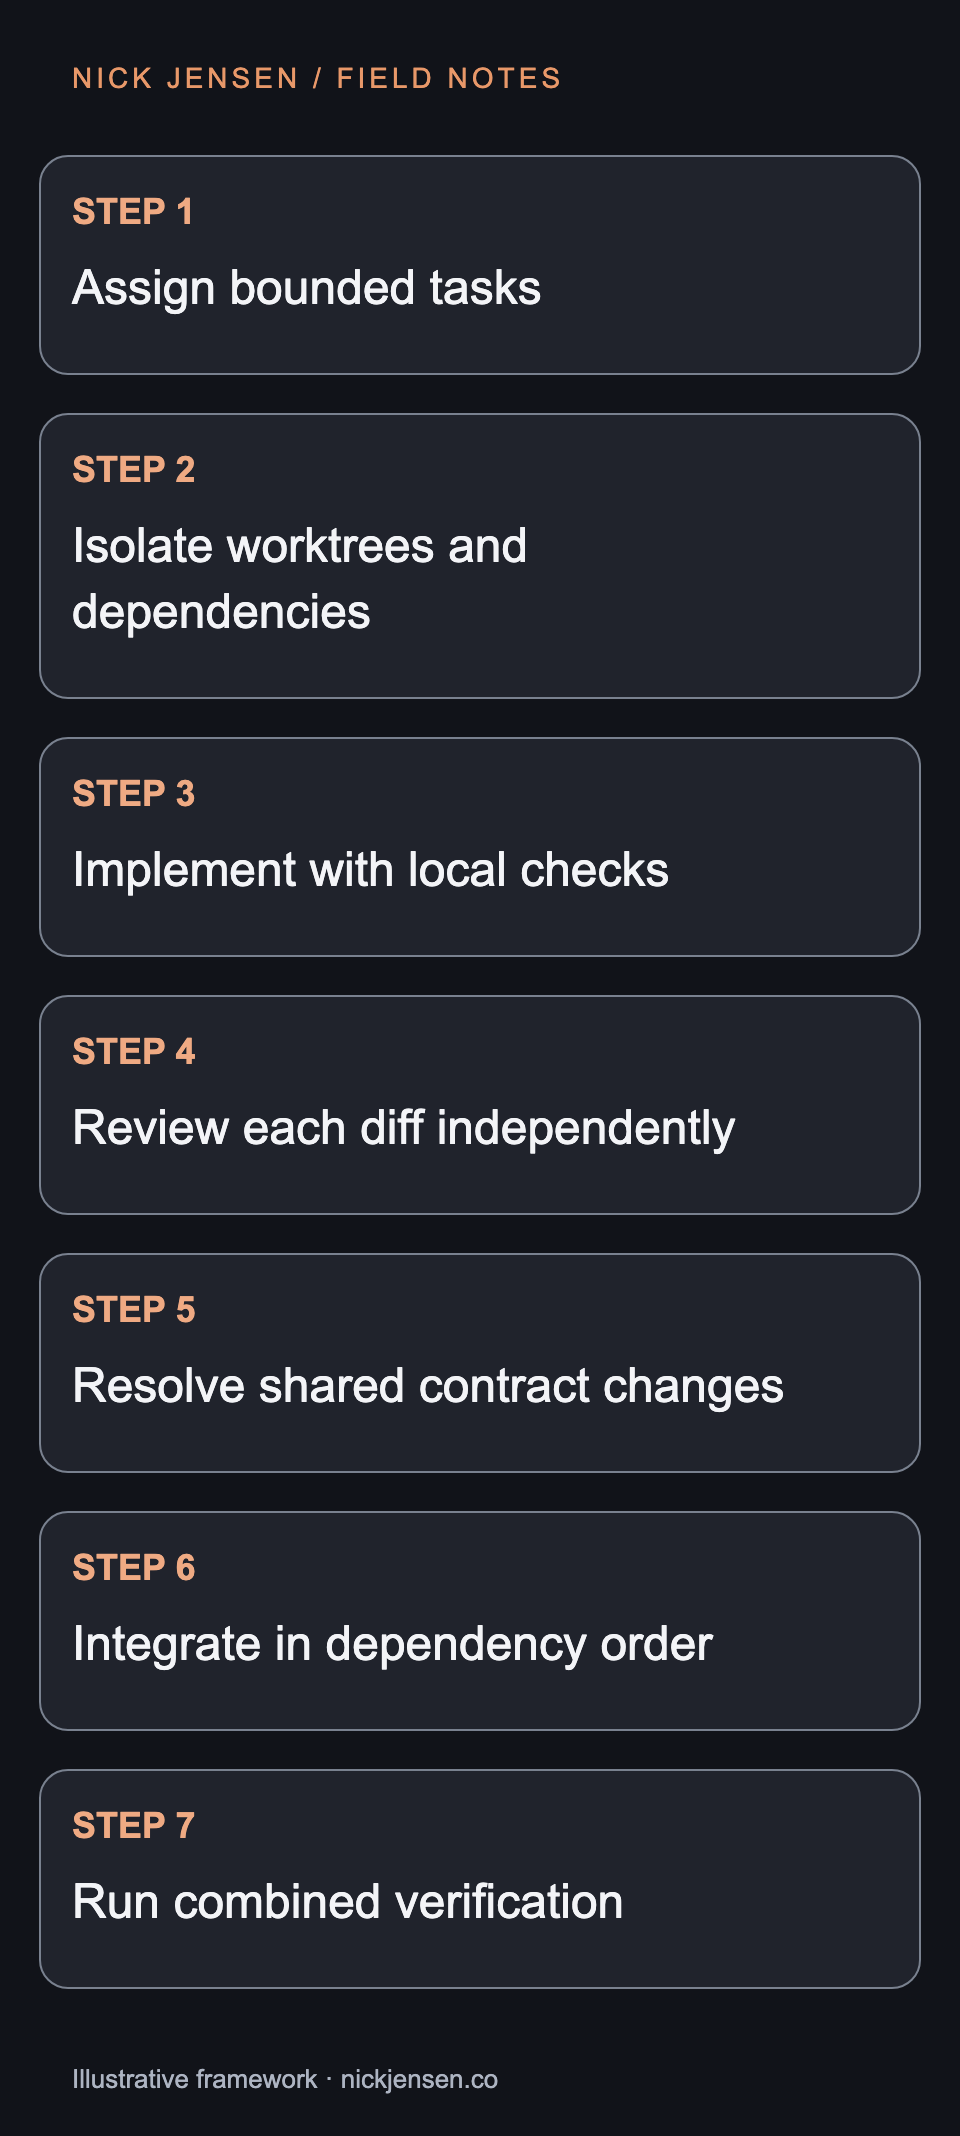
This sequence makes the integration boundary explicit: isolated branches still need a combined verification pass after shared contracts change.
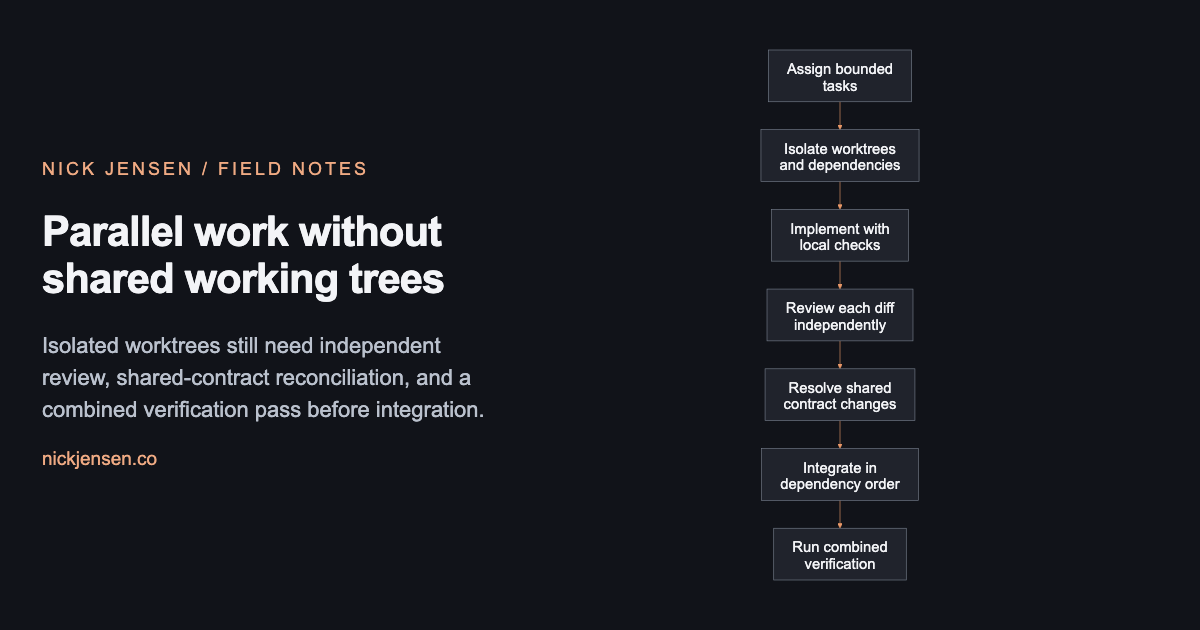
Parallel work without shared working trees
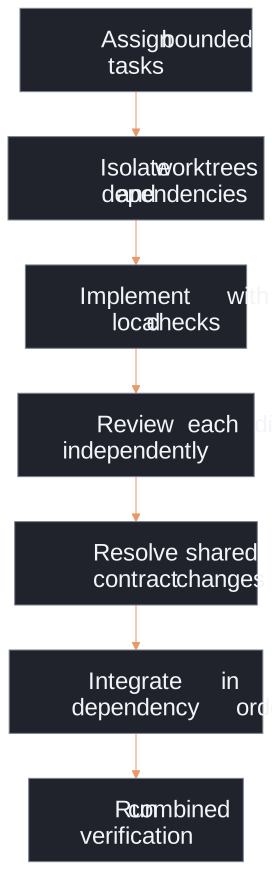
Isolated worktrees still need independent review, shared-contract reconciliation, and a combined verification pass before integration.
Illustrative framework · Graphic by Nick JensenRead the diagram as text
Flow from assign bounded tasks, then isolate worktrees and dependencies, then implement with local checks, then review each diff independently, then resolve shared contract changes, then integrate in dependency order, then run combined verification. Isolated worktrees still need independent review, shared-contract reconciliation, and a combined verification pass before integration.
From the idea to the work
Make the workflow useful in a real product.
Bring a product idea, an internal tool, or an AI-assisted workflow that needs a working implementation.